 CRE
AI for CRE Zoning and Site Feasibility: 4 Options
What a site screen actually involves
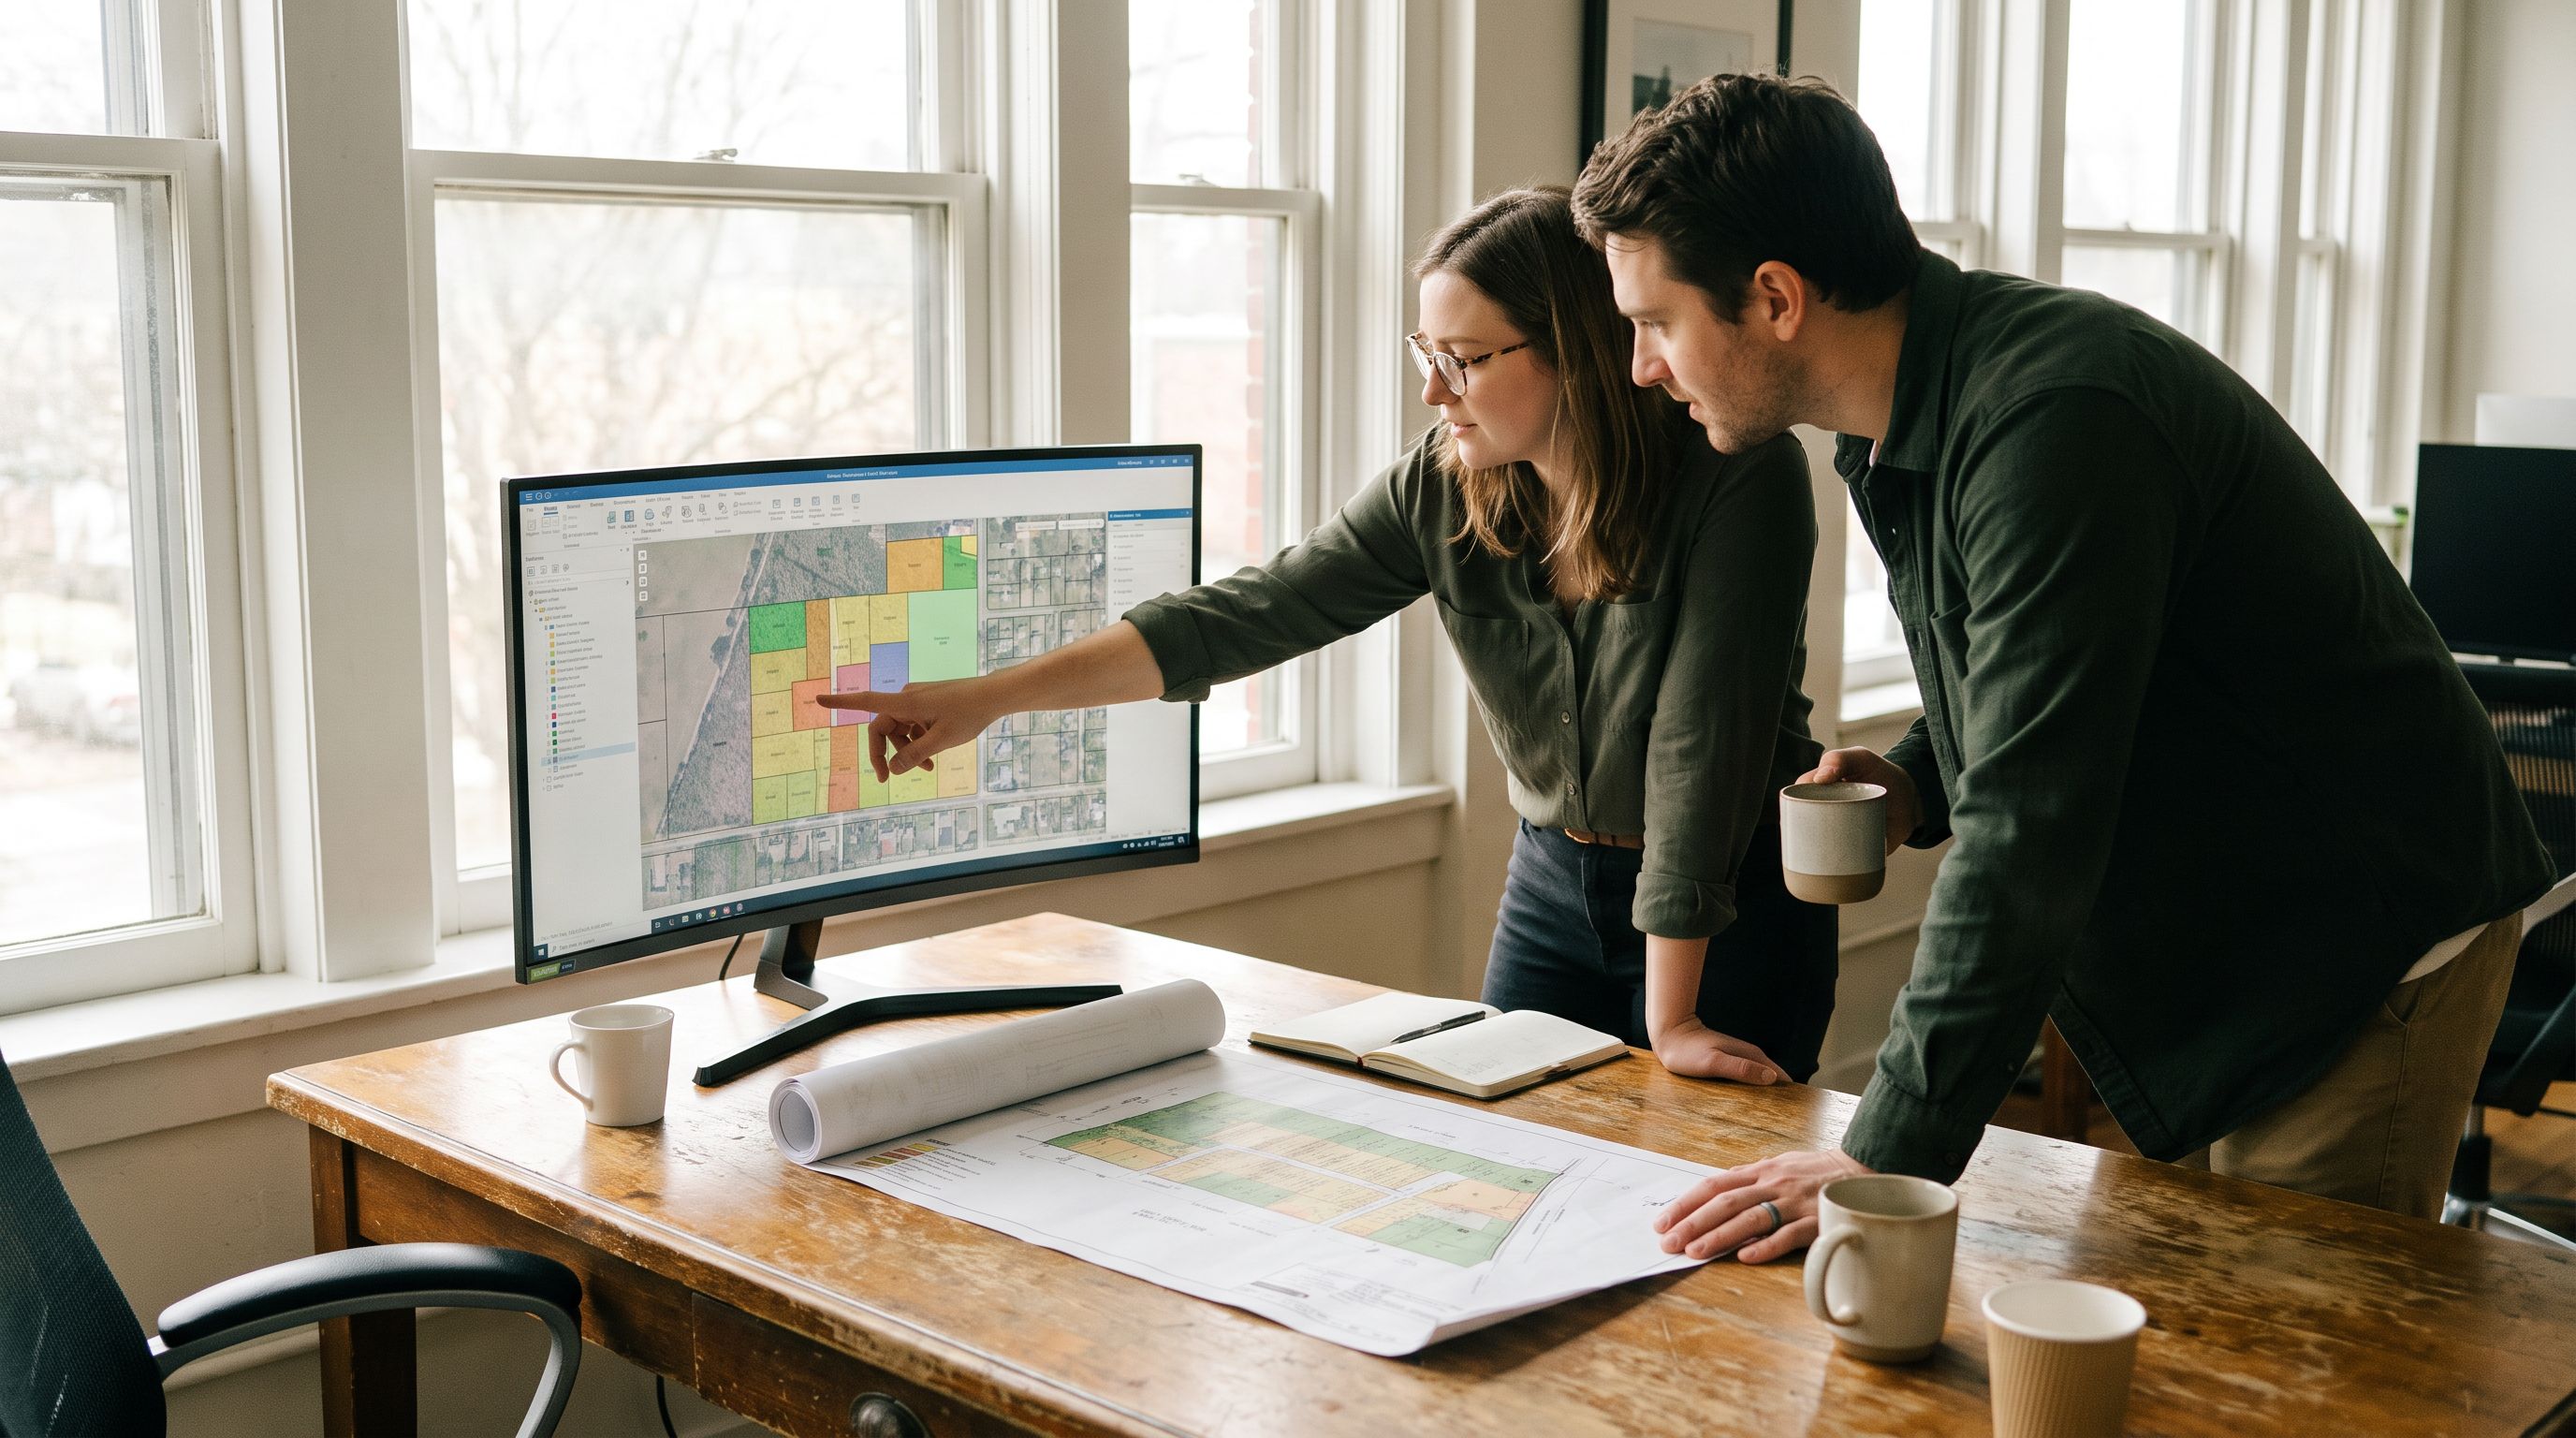
Strip the romance out of a land or redevelopment screen and it’s a sequence of lookups. Find the parcel (APN, acreage, owner, assessed value) in the county assessor or GIS portal. Pull the zoning district and read the code text — permitted and conditional uses, height, FAR, lot coverage, setbacks, parking minimums. Check overlays: historic, floodplain, airport height, transit. Check environmental and utility constraints. Then translate all of it into a one-page answer to the only question the client asked: can I put 120,000 SF of light industrial here, and what would it take?
Most of that is retrieval and summarization across a handful of public systems. That is precisely what AI agents are good at — and precisely where the failure mode is expensive, because a hallucinated 25-foot rear setback reads exactly like a real one.
Option 1: Manual research, the baseline you’re comparing against
An analyst opens the county GIS viewer, finds the parcel, pulls the zoning designation, then opens the municipal code — often hosted on a platform like Municode or General Code’s eCode360 — and reads the district table. FEMA’s Flood Map Service Center gives the flood zone. A call to the planning department resolves the ambiguities the code text doesn’t.
This is slow, it doesn’t scale past a few sites a week, and the output quality varies with who did it. But it has one property none of the AI options have by default: the person who wrote the memo knows which parts they’re sure about. Manual is also the correct permanent choice in a real set of cases — one-off deals in jurisdictions whose code isn’t digitized in any queryable form, rural counties with paper-only overlay maps, or any site where the answer hinges on a prior variance or a development agreement that only exists in a file cabinet. No amount of tooling recovers data that was never published.
Option 2: A general AI assistant with web search
Drop an address into Claude, ChatGPT, or Copilot with web search or deep research turned on and you’ll get a plausible zoning summary in under a minute. For orientation — what does M-1 generally allow in this metro, what does this code section mean in plain English — it’s genuinely useful, and the marginal cost is near zero, which is why it’s most people’s default first attempt.
The problem is that it’s non-deterministic retrieval against whatever the model found. It may read a 2019 PDF of a code that’s been amended, or a neighboring jurisdiction’s code with the same district name, or blend both. It rarely knows whether a parcel sits inside an overlay, because overlays live in GIS layers, not text. Our view: a general assistant is a reading aid for code text you’ve already located, not a source of parcel facts.
The dangerous output isn’t the one that says “I don’t know.” It’s the one that gives you a setback number with no link to where it came from.
Option 3: Off-the-shelf zoning and parcel data platforms
Vendors including Regrid (nationwide parcel data), Zoneomics, and Gridics do the unglamorous work of normalizing thousands of local codes and parcel files into structured fields you can query. Mapping and site-selection tools layer that with demographics and drive times.
When the platform covers your market, this is the highest-confidence, lowest-effort option, and it’s usually the right call. Two caveats worth pressing vendors on before you subscribe: coverage depth by jurisdiction (normalized zoning is not uniformly available everywhere — ask for a market-by-market answer, in writing, and check their documentation), and refresh cadence after a code amendment. A structured field that’s quietly stale is harder to catch than a blank one.
Option 4: A custom agent over your own sources via MCP
MCP — the Model Context Protocol, an open standard for giving an AI assistant governed access to specific tools and data — lets you build a small server that exposes exactly the sources your markets depend on: your county’s ArcGIS REST parcel and zoning endpoints, the U.S. Census Bureau’s public geocoder, FEMA’s flood layer, a licensed parcel API, your own CRM’s land pipeline, and the specific code sections you’ve already vetted.
The agent then does the multi-step job: geocode the address, hit the parcel layer, return APN and zoning district, check overlay layers, retrieve the district’s code text, and draft a standardized screen memo — with a source link and retrieval timestamp on every field. You can package the memo format as a skill so it comes out identically for every broker in the firm. The mechanics of standing one up are covered in connecting Claude to your CRE systems via a custom MCP server.
Which approach is best for your firm
There is no best AI tool for commercial real estate in the abstract — only a best fit for a specific job at a specific volume. For zoning screening, a reasonable decision rule: under a handful of sites a month, stay manual and use a general assistant to read code faster. Steady volume across many metros, buy a data platform. Steady volume concentrated in a few counties where you compete on speed — and where you already need the answer joined to your own pipeline — build. The 10-point vetting scorecard applies here without modification.
Modeling the payback with your own numbers
Don’t trust anyone’s published savings figure, including ours — we don’t have one. The formula is simple: hours per screen × screens per month × fully-loaded hourly rate = current monthly cost, then subtract subscription fees or build cost plus annual maintenance.
Here is a worked example built entirely on assumed inputs. Substitute your own; these are placeholders, not benchmarks.
With those three placeholders, 3 × 12 × 85 puts roughly $3,060 a month of analyst time into this workflow. That is arithmetic on invented inputs, not a finding. The second half matters more and is harder: recovered hours only pay if they’re reallocated to revenue work, and faster screening lets you respond to more requirements — upside you should estimate conservatively and label as an assumption. Our payback calculator walkthrough lays out the full arithmetic.
Where the human stays in the loop
IBM’s reporting on research into the boundary of AI automation makes a point worth internalizing: the limit isn’t capability, it’s accountability for judgment calls. JLL’s own analysis of where AI is changing jobs in real estate points the same direction — retrieval and drafting shift, advisory judgment doesn’t.
Keep humans on: interpreting ambiguous code language, anything involving variances or prior approvals, the planner call, and final sign-off before a memo leaves the firm. Let the agent own: geocoding, parcel lookup, overlay checks, code retrieval, first-draft memo formatting.
Two rules of thumb people ask about
The “2% rule” that surfaces in search — monthly rent at or above 2% of purchase price — originates in residential rental investing and doesn’t appear in standard commercial underwriting practice. The conventions taught in commercial coursework and appraisal practice are different metrics entirely: cap rate, debt service coverage ratio, price per SF against comps, and untrended yield-on-cost. Use those.
Similarly, there is no formal “30% rule in AI.” It’s shorthand different commentators use for different things — a share of a task an agent handles, a share of a workforce affected. Our opinion, stated as opinion: pick your own threshold per workflow by measuring output quality, and ignore any round number presented as an industry law.
A two-week pilot
-
Pick one county and ten real parcels
Choose sites where you already know the correct answer. This is your answer key. -
Run all four approaches against them
Manual, general assistant, platform trial, and a rough scripted prototype. Score each on accuracy against your key, source traceability, and elapsed time. -
Set a pass threshold before you score
We’re not going to hand you a universal number, because the right bar depends on whether the memo drives price. Our opinion as a starting point: any approach that misses more than one field in ten, or returns a number you can’t trace to a source link, fails for client-facing use and is demoted to internal orientation only. -
Count the silent failures separately
Wrong-but-confident answers are a different category from blanks. Weight them heavily. -
Standardize the memo before you automate it
Agree on the output format and required citations first. A skill can only enforce a standard that exists. -
Decide by volume and market concentration
If a subscription clears the bar, buy it. Build only where coverage gaps or CRM integration make it necessary.
The honest summary: this workflow is a strong candidate for agentic automation because the inputs are public and structured, and a weak candidate for blind trust because the stakes are legal. Automate the retrieval, standardize the memo, and keep the planner’s phone number.
Not sure where to start?
Get a free automation audit: we map your deal pipeline, marketing, and back-office workflows and show you what's worth automating — before you spend a dollar.
Get a free automation auditRelated guides
AI Texting for CRE Broker Follow-Up: 4 Options Compared
Compare four ways to run AI text-message follow-up for commercial real estate brokers — manual, CRM add-on, conversational SMS vendor, or a custom MCP agent.
Read guide →
AI for CRE Estoppels and SNDAs: 4 Options Compared
Chasing tenant estoppel certificates and SNDAs before closing? Compare manual, template automation, platform AI, and a custom AI agent for commercial real estate.
Read guide →
AI for Net Effective Rent Analysis: 4 CRE Options
Comparing four ways to turn landlord lease proposals into net effective rent: Excel, platform AI features, a general AI assistant, and a custom MCP agent.
Read guide →